

MIT researchers studied which language patterns a neural network used to classify news articles. Their 2018 work also tested what happened when the subject of the test articles had been excluded from training, a harder task than recognizing familiar topics.
The study helps explain a classifier’s decisions. It does not establish a list of words that proves a story false, or a way to replace checking its evidence. MIT’s account of the research emphasizes the need for more testing before practical use.
Correction, November 5, 2026: The experimental results do not establish that the model is unbiased or that highlighted words prove an article false. The reported accuracy describes classification against the study’s dataset labels.
How the classifier used language
Nicole O’Brien, Sophia Latessa, Georgios Evangelopoulos and Xavier Boix wrote the research paper. The AI for Social Good workshop at NeurIPS 2018 lists it as a poster presentation.
The model processed three-word patterns using a convolutional neural network. The researchers traced influential activations back to the words in an article. That made it possible to inspect which passages contributed to a prediction; a visible explanation does not independently verify the underlying claim.
Why the evaluation design matters
The paper describes news collected around the 2016 US presidential election. It used a Kaggle fake-news dataset and articles from The New York Times and The Guardian. The authors acknowledged that source-based labels could include mistakes; those labels were not an independent factual audit of every article.
After cleaning, the dataset contained 16,400 articles. A test holding out articles containing “Trump” reached about 88% accuracy; a test on topics represented in training reached about 94%. These were different experimental conditions, not a guaranteed accuracy rate for arbitrary news on the web.
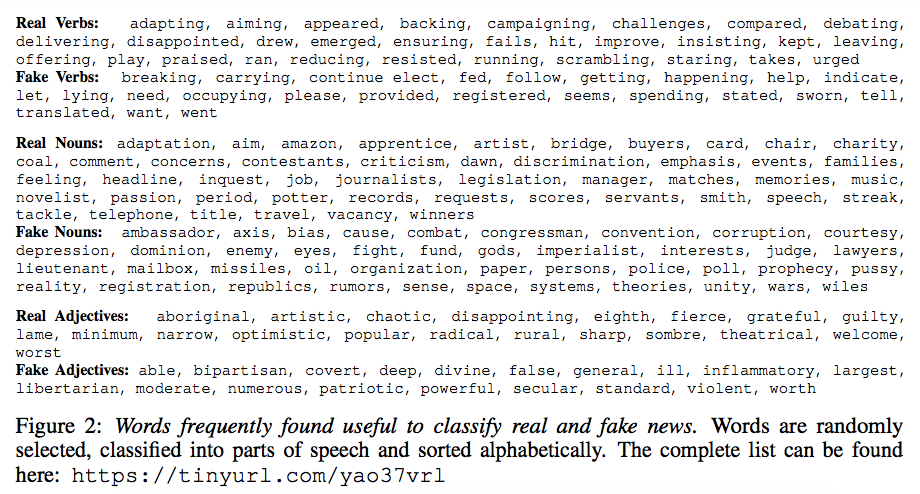
The authors’ complete word lists are research outputs, not a blacklist for readers. An expression can contribute to one prediction without being useful in every article where it appears.
What remains unproven
Removing one topic from training does not remove every possible bias. The choice of news outlets can also leave the model learning their writing styles. Explaining a prediction and demonstrating that it generalizes are separate questions. Readers still need to examine the source, supporting evidence and context.
For related coverage, see TechEngage’s AI section.



Share Your Thoughts